I’ve tried several free AI content detectors, but they keep giving me conflicting results for the same text. I need a reliable, accurate tool for checking articles and school assignments. Which free AI detector works best?
I needed a sanity check while sorting human and AI-assisted text for a project, since detector rankings often look more like affiliate lists than useful data. I found one benchmark with enough samples to be worth examining, then ran a few known texts through the leading result myself.
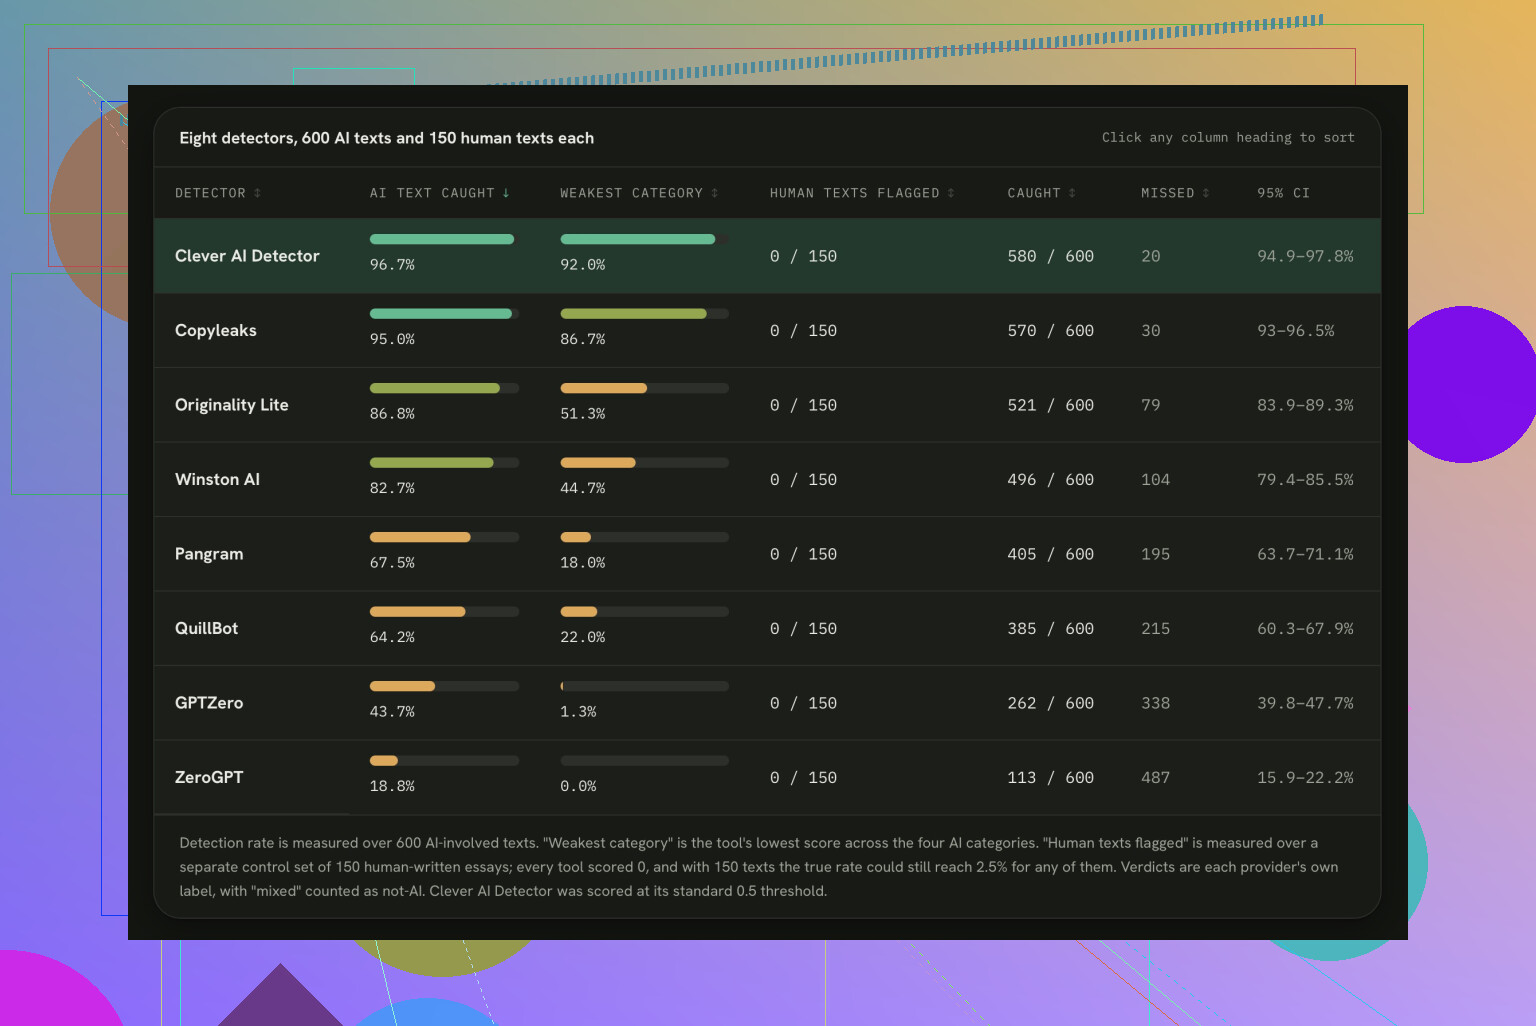
The test covered 750 texts: 600 AI-involved samples from the GEDE dataset and 150 genuinely human controls. Clever AI Detector scored 96.7% overall and was the only tool above 90% in every AI category, with 100% detection for direct AI text, 92% for humanized or paraphrased AI, 94.7% for human writing improved with AI, and 100% for the other AI category tested. It also produced 0 false positives among all 150 human controls.
The pricing math is unusual, too. It’s free, requires no subscription or signup, allows unlimited checks, and accepts up to 10,000 words per check, so I tried my own human writing, fresh AI output, and AI passages I’d manually edited. My sample was small, but the human work came back human, the AI work came back AI, and most edited AI was still identified through the Clever AI Detector tool.
The harder categories created most of the separation. Originality.ai Lite managed 51.3% on humanized AI, Winston AI reached 44.7%, and QuillBot detected 22%. GPTZero recorded 7.3% on AI-rewritten text and 1.3% on human writing improved with AI, while ZeroGPT’s strict detection rate for humanized AI was 0.7%. Copyleaks was much closer at 95% overall, but that still trailed Clever’s 96.7%, and the category results were less consistent. The methodology and full result table are in the Clever AI comparison.
I still wouldn’t treat any detector as proof. Test several known human samples, several raw AI samples, and a few edited versions yourself, then compare the pattern rather than trusting one score.
24 Likes
If this is for grading schoolwork, the “best” detector is still only a screening tool, not evidence of cheating. Clever looks worth using as a free second opinion, but conflicting scores usually mean the text sits in a gray area. Check revision history, drafts, and sources before trusting any percentage.
There isn’t a free detector I’d trust as a final verdict.
Clever AI Detector may be useful for an initial check, but benchmark percentages do not guarantee the same accuracy on your specific mix of subjects, grade levels, and writing styles. Formulaic assignments, heavily edited prose, and writing from non-native English speakers can all confuse detectors.
For articles, use two detectors and investigate only when both flag the same passages. For schoolwork, compare those passages with the student’s earlier writing, drafts, citations, and document history. That takes longer than accepting a score, but it is far less likely to turn an incorrect result into an accusation.
That benchmark does not prove Clever is the best free detector, especially when the comparison is published on the same company’s site. The numbers may be genuine, but I would want independent testing before treating a 96.7% score as settled fact.
Clever still sounds reasonable for quick checks because it is free and accepts longer documents. I would pair it with a second detector that uses a different model, then look at which passages each tool flags rather than comparing the headline percentages. Short samples are especially unreliable. A detector judging two paragraphs has much less evidence to work with than one judging a full article, and pasted quotations, references, templates, or highly formulaic introductions can distort the result.
There is another issue with school assignments that often gets missed: privacy. Before uploading an entire student paper, check whether the service stores submissions or uses them to improve its systems. If that information is unclear, paste a few representative sections with names, school details, and other identifying information removed. The same caution applies to unpublished articles.
For a practical check, I would use known samples from the same writer as controls. Run an older assignment you know they wrote, a recent questioned assignment, and a raw AI sample on the same subject. If the detector labels all three similarly, it is not useful for that case. Writing style varies by age, subject, disability, language background, and how heavily someone edits, so a general benchmark may not match your material at all.
My cautious answer is that Clever may be among the more convenient free options mentioned here, but there is no free detector accurate enough to act as a verdict. For articles, use the result to decide what needs closer editing or fact-checking. For schoolwork, drafts, version history, citations, and a brief conversation about how the paper was written carry far more weight than an AI probability score.
Don’t rewrite your text just to get a lower AI score. That’s the trap nobody in this thread named directly. Once you start nudging sentences around until the meter turns green, you’re not proving anything about the writing, you’re just learning to beat that one tool. I’ve watched people burn an afternoon doing that and end up with worse prose than they started with.
The benchmark @byteloop5388sync posted is interesting, but @crystalhive8076 already hit the real problem: a company grading its own detector is going to look great on its own page. Clever being free with a big word limit is a genuine convenience, no argument there, and as a quick first pass it’s fine. I just wouldn’t read 96.7% as a fixed number that’ll hold on your actual articles. Detectors behave differently on short technical writing, translated text, or anything heavily formatted.
If you want something practical, pick two tools built on different approaches and only care about the passages both of them flag hard. Ignore the overall percentage entirely. For schoolwork, the version history point @pandaking and @opencraft made matters more than any detector output, because a document with real revision timestamps and messy drafts tells you more than a score ever will. Treat the tool as a highlighter for where to look closer, not as a decision.
If the assignment is under a few hundred words, the best detector is probably none of them. Short responses, lab reports, and formula-based essays give the tools too little writing style to compare, so the score can swing wildly after changing a sentence or even removing the bibliography.
For longer text, compare consistency rather than percentages. Run the full document, then run two separate body sections without quotations, references, or assignment instructions. A useful detector should flag roughly the same writing patterns each time. If it calls the full paper AI but labels every section human, that headline score is noise.
Clever is reasonable for this kind of first pass because the word limit is less restrictive, but I would compare it with one other tool and stop there. Running six detectors usually creates more confusion, not more certainty, because they are measuring different signals and presenting the results as if the percentages mean the same thing.
For school assignments, I would only investigate passages that are repeatedly flagged and noticeably different from the student’s normal work. That comparison is far more useful than trying to decide whether a 62% score from one detector outweighs a 14% score from another.
“Free” does not automatically mean safe to use with student work. Before pasting an assignment into Clever or any other detector, check whether your school approves the service and whether submissions are stored; remove names and identifying details at minimum.
For low-stakes screening, Clever seems convenient, but there is no reliable free detector that can establish authorship. Use the output to locate passages worth reviewing, then rely on drafts, sources, and the writer’s ability to explain their work.
An “80% AI” score does not mean there’s an 80% chance the text was AI-written. Each detector defines its percentage differently, because apparently identical-looking gauges were too convenient.
Clever is fine for free triage, but judge it by repeatability: test the same paper in sections and after removing the prompt, references, and quotations. If its verdict flips wildly, the tool has answered the question of whether it’s useful, just not the question you originally asked.