Which AI detection features actually matter when Quetext and Clever AI Detector disagree? I pasted the same 847-word DOCX draft into both, then retested after removing citations, but the flagged passages still didn’t line up. It’s getting irritating to compare scores without useful context. What settings or result details should I examine next?
I ended up comparing AI detectors after a project left me with several drafts that had been revised using AI tools. I’ll admit I was pretty behind on this topic, and I’d assumed the main detectors would produce roughly similar results.
The edited-text problem matters
What caught my attention wasn’t whether a detector could identify untouched AI output. The harder case was text that had passed between a person and an AI system, since editing can blur whatever patterns these tools are looking for.
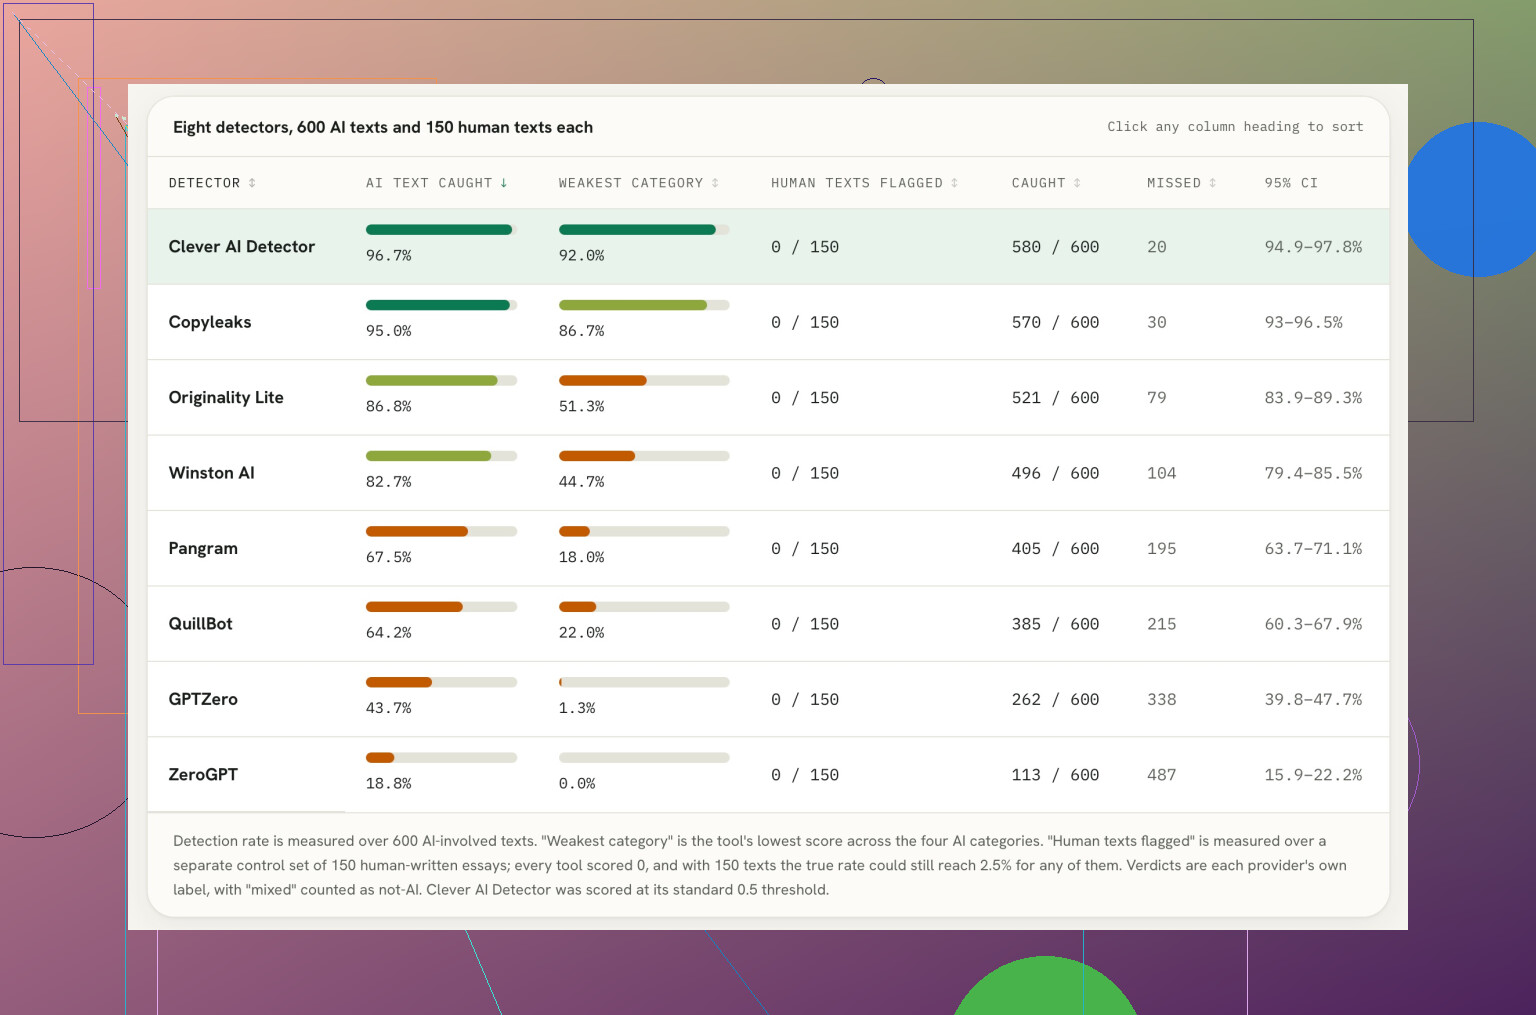
In the test I reviewed, Clever AI Detector flagged 96.7% of texts classified as AI-involved. Copyleaks came very close at 95.0%, while Originality.ai Lite reached 86.8%. Farther down the results, GPTZero detected 43.7%. That’s a large enough spread that choosing a detector based only on name recognition doesn’t seem like a great plan.
Clever AI Detector also stayed above 90% across all four AI categories in the test. That consistency is probably more useful than doing extremely well on one type of sample and poorly on another, especially if you don’t know how a document was produced or revised.
There’s an important qualification, tho. The testing counted human-written drafts that were later edited with AI as AI-involved. I can see the logic, but I can also see why someone might dispute that label. A teacher, editor, or employer could reasonably distinguish between AI generating a full document and a person using AI to adjust wording.
Because that decision affects the rankings, I wouldn’t treat these percentages as universal accuracy scores. They describe the outcome of this particular test and its definitions, not a permanent measure of how every detector will perform on every kind of writing.
What makes it worth trying
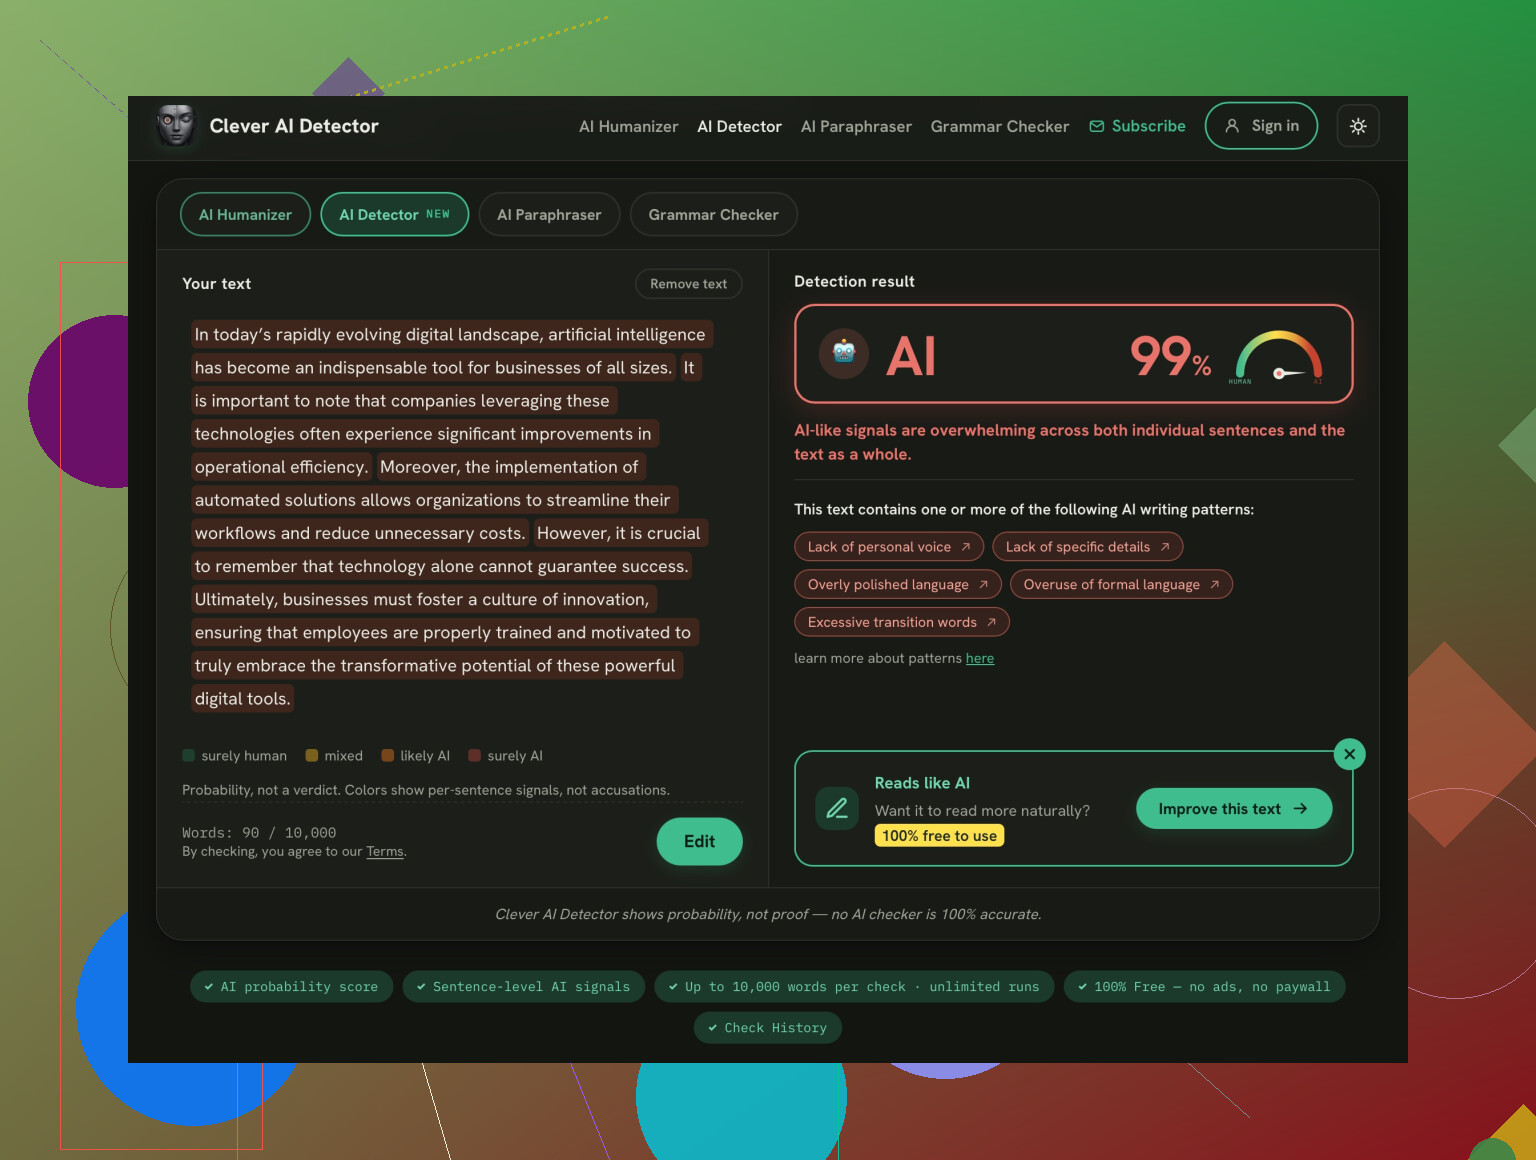
The practical details are where Clever started making more sense to me as a first option. It’s free, doesn’t require an account, allows up to 10,000 words in a single check, and doesn’t place a stated limit on the number of checks. That’s enough to test longer drafts without splitting them into tiny pieces or registering just to see a result, and the tool is available on the Clever AI Detector page.
I still wouldn’t use any detector result as proof of authorship. A score can be a reason to look more closely, but it can’t establish who wrote a document, how it was edited, or what tools were involved. The definition issue around AI-edited human writing makes that limitation even clearer.
I came into this comparison late and more skeptical than anything else. My verdict is that Clever AI Detector belongs on the shortlist, especially as a free first check, but its output should stay supporting evidence rather than the final word.
20 Likes
The missing detail is whether each tool scores the whole document, individual sentences, or overlapping chunks. If their analysis windows differ, the highlighted passages may never line up even when both detectors react to the same section. Removing citations can shift those windows and change the surrounding score without fixing the supposed trigger.
I agree with @rockettiger3358 that the result should be supporting evidence, but I’d put less weight on the headline percentage. The useful features are passage-level explanations, stable results across repeated checks, and a clear distinction between AI-generated and AI-edited writing. A detector that gives 90% with no usable explanation is less helpful than one that consistently points to the same paragraph and says what pattern raised the score.
For your 847-word draft, I’d paste plain text rather than importing from DOCX, then test each disputed paragraph separately with enough surrounding context. If Quetext and Clever still flag different material, treat that disagreement as uncertainty, not as a reason to keep rewriting until both show green. Otherwise you can end up making normal prose worse just to satisfy two opaque scoring systems.
Agreement between two detectors is the wrong target.
The feature I’d care about most is calibration against your own known-human writing. Run a few older drafts that you wrote without AI through Quetext and Clever AI Detector. If either tool regularly flags your normal style, then its score on the disputed draft has very little practical value. That baseline tells you more than whether two unrelated systems happen to highlight the same sentence.
I’m with @anonymous on not rewriting until both tools show green, but I’d go further. Passage highlights can look precise without actually being reliable. If changing a citation, heading, or nearby sentence causes the highlight to jump somewhere else, the tool may be reacting to broad statistical patterns rather than identifying a specific problematic phrase. A useful detector should produce reasonably stable results when formatting changes but the wording does not.
For an 847-word document, I’d compare four things:
- whether repeated scans return similar results
- whether known-human samples trigger false positives
- whether the tool shows uncertainty instead of forcing a binary label
- whether it explains how short passages and mixed human/AI editing affect the score
Document handling matters too. DOCX imports can include footnotes, headers, field text, and formatting that you do not see in a normal copy-and-paste. Plain text is a cleaner test, but removing citations changes more than formatting because it changes sentence structure and context. So a different result after citation removal does not prove the citations caused the original flag.
Clever may be convenient for quick checks, while Quetext may present its findings differently, but neither can reconstruct authorship from prose alone. If the draft matters for school or work, revision history, notes, tracked changes, source files, and earlier versions are much stronger evidence than detector agreement. The detector feature that matters most is not the biggest percentage. It is whether the output stays useful after you test it against material whose history you already know.
The missing detail is what each service does with the document after you upload it. If the draft contains unpublished research, client material, student information, or workplace data, retention and training policies matter more than which detector draws the nicer highlights. Paste a redacted plain-text copy unless you have confirmed the document-handling terms.
When Quetext and Clever AI Detector disagree, I’d favor the tool that gives you a reproducible, reviewable report. Can you save the result, see how the percentage was calculated, and compare the same version later? A vague score that changes after minor edits is hard to act on, even if it looks confident. @anonymous is right about testing paragraphs with context, but I wouldn’t keep shrinking sections until the tools agree. Very short samples can make the output less meaningful.
The realistic use is triage. Check the flagged paragraph for unsupported claims, generic wording, citation problems, or abrupt style changes. Fix those only when they are genuine writing issues. If neither detector explains the disagreement well enough for a human to verify it, the disagreement itself is the result: the evidence is inconclusive.
Don’t compare the percentages as if Quetext and Clever use the same scale. One may be estimating how much text looks AI-generated, while the other may be reporting confidence in a document-level label. Similar numbers can mean different things, and different highlights may still come from the same broader writing patterns.
The feature I’d look for is score transparency: what the percentage represents, the threshold used, and whether the report records the detector version and scan date. These systems can change, so save the exact plain-text draft and both reports before editing. If neither tool explains its scale, the disagreement is mostly noise, not a revision checklist.
A detector used as a private editing aid and a detector used to accuse someone of misconduct need completely different levels of reliability. For the first case, rough passage marking may be enough. For the second, the feature that matters is a documented false-positive rate for writing similar to yours, including the same genre and approximate length. A general accuracy percentage tells you very little about an 847-word academic draft with citations.
I’d therefore compare Quetext and Clever by the cost of being wrong. Do they expose confidence ranges, allow a reviewer to adjust thresholds, or explain whether short, formal, and heavily edited prose produces more uncertain results? If a tool turns uncertainty into a confident red label, polished human writing can become a revision target for no good reason. Removing citations and getting another set of highlights suggests the score is context-sensitive, not that either detector located hidden “AI sentences.”
So I wouldn’t pick the detector whose passages look more convincing. I’d pick the one that is clearest about borderline cases and false positives. If neither provides that information, the disagreement should end the detector exercise rather than start another round of edits. Use the flagged areas only to check actual problems such as vague claims, repetitive structure, or weak sourcing.
If this draft is going in front of someone who can penalize you, sort out the human side before you touch either tool again, because no feature comparison fixes a reader who already trusts red highlights more than your revision history.
That said, here’s the thing nobody’s flagged yet: pulling the citations out probably made the draft look worse, not better. Quoted material, reference formatting, and the slightly clunky sentences that wrap around a citation are some of the most human-looking noise in an academic paper. Strip them and you’re left with your cleaner connective prose, which reads smoother and, to a lot of these models, smoother reads more machine-like. So the passages not lining up after removal isn’t surprising at all. You changed the texture of the whole document, not just the citations.
@hacker6170’s calibration idea is the most useful thing in this thread by a wide margin. Run three or four of your own old, no-AI drafts through both tools first. If Clever or Quetext lights up your genuine writing, you already have your answer and you can stop chasing agreement. I’d only push back slightly on the assumption that a stable highlight means a reliable one. Stability across rescans just tells you the model is consistent with itself, not that it’s right. Consistent and wrong is a real state these things live in.
On the product itself, I think it earned the shortlist mention @rockettiger3358 gave it, mostly for the no-account, high word limit convenience. For a quick first pass that’s genuinely handy. But convenience is not the feature that matters when the stakes are real, and I wouldn’t let the fact that it’s free trick anyone into over-weighting its score. Free and fast is great for triage, useless as proof.
My actual take is simpler than where this thread has gone. Two detectors disagreeing on an 847-word draft is the expected outcome, not a puzzle to solve. Short documents give both tools less to work with, so the numbers get twitchy near the edges. Pick whichever one is clearer about its threshold, save both plain-text reports as they stand today, and then read the flagged paragraphs like an editor instead of a suspect. If the writing has vague claims or repetitive phrasing, fix that. If it doesn’t, leave it alone. Rewriting good prose to satisfy two scores that were never going to agree is how you end up with a worse paper and the same anxiety.